What Is CMDB? Configuration Management Database Explained
Most IT teams know what hardware and software they have bought. Far fewer can say how each component is configured, or which services will go down if it fails. A configuration management database (CMDB) closes that gap, and within the ITIL framework it is the reference point for incident, problem and change decisions.
Many CMDB projects still fall short of that goal. Gartner has found that heads of I&O often miss the full value of their CMDB, mainly because its data is not aligned with the service portfolio. This guide explains how a CMDB works, using the CI model and setup steps from our ServiceOps documentation.
What Is CMDB?
CMDB stands for configuration management database, a repository that stores configuration items, their attributes and the relationships that link them. ITIL 4 defines a CI as any component that needs to be managed in order to deliver an IT service, so the scope goes well beyond hardware.
The CMDB supports the service configuration management practice in ITIL 4. Its job is to hold a current view of each service, so a technician can check what a business service depends on before touching any part of it.
A CMDB is often confused with an asset register, and the difference matters. An asset register tells you what was purchased and when. A CMDB also shows where a component runs and what else will be affected if it fails, and that relationship data is what separates the two.
The short video below walks through how a CMDB is used in day-to-day IT work.
What Is a Configuration Item (CI)?
A configuration item is any component placed under configuration control because a service depends on it. In ServiceOps, CIs are organized into a type hierarchy, and each type has its own form with custom fields, validation rules and suggested relationships.
Our configuration items documentation lists four standard high-level types, and you can nest up to five levels of custom sub-types beneath each one, such as Hardware > Servers > Web Servers.
CI Type | What It Covers | Example |
Hardware | Physical and virtual servers, storage, desktops and laptops | A Dell PowerEdge R740 in Data Center A |
Software | Operating systems, applications and installed packages | The web application running on that server |
Service | A business service built from many CIs | Online Checkout |
Network | Switches, routers, firewalls and other network components | The switch port the server connects to |
Every CI stores a unique ID, name, type, status, business impact, location and ownership details. Type-specific attributes add fields such as manufacturer, model, serial number, software version and license information. The sample physical server record in our docs shows what a complete hardware CI looks like.
Field | Sample Value |
Type | Physical Server |
Hostname | PROD-WEB-01 |
IP address | 10.0.1.15 |
Status | In Production |
Owner | IT Infrastructure Team |
Location | Data Center A, Rack 2, Unit 5 |
Model | Dell PowerEdge R740 |
Warranty expiry | 2027-08-20 |
Each CI also carries a status that reflects where it sits in its life. The docs describe four: Operational for CIs actively delivering a service, Non-Operational for CIs available but not in use, In Maintenance for planned downtime and Retired for decommissioned items.
How Does a CMDB Work?
A CMDB works by collecting CI data, classifying it, linking CIs to each other and keeping those records in sync until each CI is retired. Our docs describe this as a seven-stage CI lifecycle.
Discovery and identification: Agent-based or agentless scanning finds devices on the network.
Classification: Discovered attributes such as the operating system, hardware specs and network configuration are identified.
CI creation: Records are created through discovery, manual entry or asset-based sync rules.
Relationship mapping: Dependencies between CIs are recorded, which is what makes impact analysis possible.
Synchronization and status mapping: Asset and CI lifecycles are linked, so the two records stay consistent.
Auditing and maintenance: Sync rules and discovery preferences are refined as the environment changes.
Retirement and archiving: The CI status is set to Retired and the record is archived.
Discovery is the stage that decides whether the data stays accurate. Automated asset discovery runs through agents on Windows, macOS and Linux endpoints, or agentlessly over SSH, SNMP and WMI, and it picks up changes a manual record would miss.
Some CIs, such as a business service or a contract, cannot be discovered on a network. For those, the CMDB FAQ lists three other routes: manual entry through Create New > Add CI, a sync rule configured on the CI type, or an automation workflow that runs the Execute Sync Rule action.
How Does a CMDB Support ITSM Processes?
A CMDB adds value only when other ITSM processes read from it. The table below shows how each core process uses CI data in day-to-day work.
ITSM Process | How It Uses the CMDB | Typical Question Answered |
Incident management | Links each ticket to the affected CI and shows its dependencies | Which service is down if this switch fails? |
Problem management | Uses relationship data to trace the root cause of recurring incidents | Do these 5 incidents trace back to one database? |
Change management | Runs impact analysis before a change is approved | What else breaks if this server is patched this weekend? |
Release management | Confirms which CIs a release will touch | Which applications need regression testing? |
Asset management | Keeps the operational CI record in sync with the financial asset record | Is every licensed server actually in production? |
Of the five, change management usually sees the quickest return. Change impact analysis depends on relationship data, and in ServiceOps the impact view feeds directly into Change Advisory Board approval decisions.
Getting a change wrong is expensive. The ITIC 2024 Hourly Cost of Downtime Report found that an hour of downtime costs more than $300,000 at over 90% of mid-size and large enterprises, and a failed change is one of the more avoidable ways to cause it.
What Are the Benefits of a CMDB?
The benefits of a CMDB fall into four areas: planning, operations, cost control and compliance. Each one depends on the same accurate CI and relationship data.
Planning: Capacity and refresh planning can be based on what is actually deployed. A team can see which business services still run on end-of-life hardware before the budget cycle closes.
Operations: Incidents get diagnosed faster when the technician can see what a failed CI connects to. Changes get approved with a clearer view of risk, and repeat incidents are easier to group under one problem.
Cost control: Licenses, contracts and hardware can be tied to the services that use them. Unused software and idle servers then show up as CIs with no relationship to any live service.
Compliance: The CMDB gives auditors a detailed, auditable record of your infrastructure and its configuration, which makes security and compliance audits easier to support.
CMDB vs IT Asset Management: What Is the Difference?
A CMDB and IT asset management (ITAM) both hold records about IT components, but they answer different questions. ITAM tracks the financial and contractual lifecycle of an asset from purchase to disposal, while the CMDB tracks how a live component is configured and what depends on it.
The table below summarizes the main differences, and our guide to CMDB vs ITAM covers the full comparison.
Aspect | CMDB | IT Asset Management |
Main question | How is this configured, and what depends on it? | What do we own, and what does it cost? |
Record unit | Configuration item | Asset |
Key data | Attributes and relationships | Cost, contract, warranty and depreciation |
Main users | Service desk, change and problem teams | Procurement, finance and IT asset managers |
Lifecycle focus | While the component is in service | Purchase to disposal |
The two work best when they are connected. In ServiceOps, sync rules can create an asset from a CI or a CI from an asset, and CI Asset Status Mapping keeps both lifecycles aligned. When an asset reaches In Use, its CI can be set to Operational or Non-Operational, and when the asset moves to maintenance or retirement, the CI status updates to match.
Why Do CMDB Projects Fail?
CMDB projects usually fail because of scope and ownership, and the technology is seldom the cause. Four failure patterns come up again and again in the service desks we work with.
1. The Scope Is Too Wide
Teams try to load every component on day one. The database fills with low-value records that nobody maintains, and trust in the data drops within a few months. Our docs recommend starting with one or two critical services for this reason.
2. Nobody Owns the Data
When no named owner is accountable for each CI type, attributes go stale and relationships are rarely updated after a change goes in.
3. Discovery Is Manual
Records that depend on manual entry drift as soon as a server is rebuilt or a workload moves. Scheduled automated discovery is the only reliable way to keep pace with that rate of change.
4. Nothing Reads From It
A CMDB that is not linked to incident and change records soon gets treated as documentation. Daily use keeps the data accurate, because the people relying on it spot and report errors quickly.
How Do You Build a CMDB That Stays Accurate?
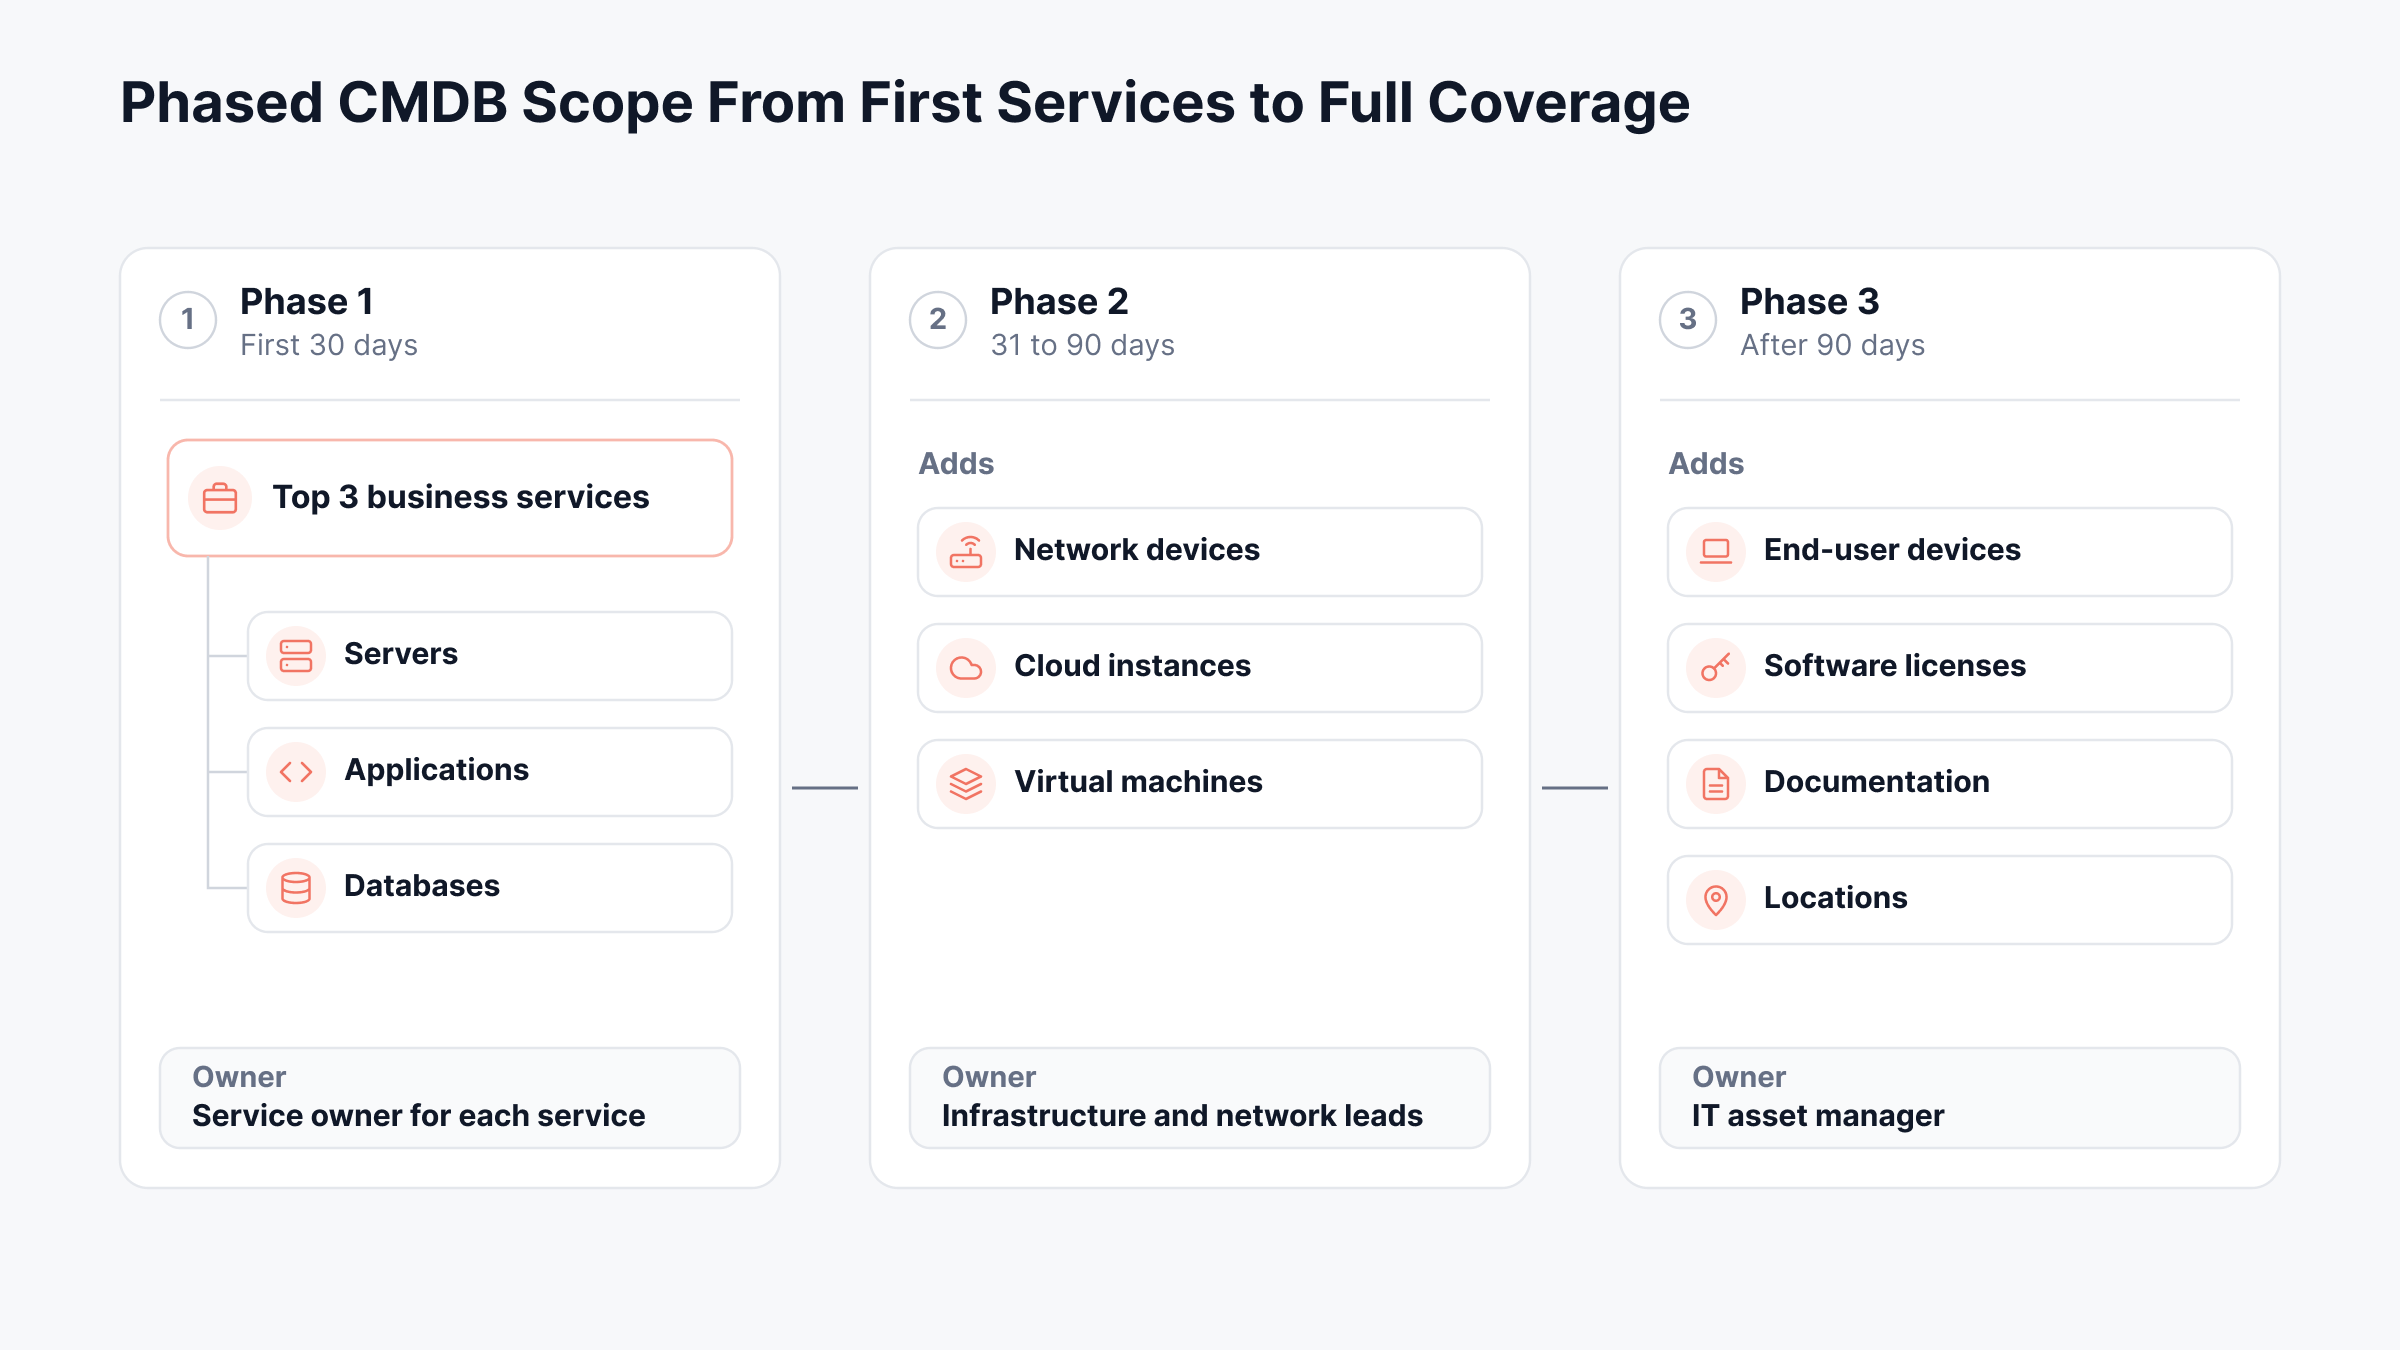
You build an accurate CMDB in phases, starting with the services that matter most and widening the scope only once each phase is owned and maintained. The table below sets out the phased approach we recommend.
Phase | CI Types to Include | Owner | Why at This Stage |
First 30 days | Your top 3 business services and the servers, applications and databases behind them | Service owner for each service | Gives change and incident teams immediate value on the services users notice |
31 to 90 days | Network devices, cloud instances and virtual machines | Infrastructure and network leads | Fills in the dependencies that most often cause cross-team incidents |
After 90 days | End-user devices, software licenses, documentation and locations | IT asset manager | Adds cost and compliance value once the core data is trusted |
Close each phase with a short audit that checks a sample of CIs against the live environment and traces every gap back to a discovery or ownership issue. If a phase fails that check, hold the scope where it is until the gaps are fixed.
Relationship data needs the same discipline. CI relationship mapping works best when discovery creates most relationships and the service owner confirms the business-level links, with each relationship reviewed during change reviews and post-incident analysis.
What Our ServiceOps Docs Show About Running a CMDB
Our CMDB documentation covers several settings that make the phased approach easier to sustain. These five are worth configuring before your first rollout phase.
1. Set Up Access and Admin Settings First
Managing the CMDB requires a CMDB license and the CMDB Specialist Technician role, and running sync rules also needs the Manage CMDB permission. The Admin > CMDB section then holds four settings: CI Type, CI Status, CI Group and CI Custom Rules.
2. Relationships Run in Both Directions
The CI relationships documentation describes a bidirectional model, where every link has a Direct and an Inverse type. For example, WebApp-01 runs on Server-01, and Server-01 hosts WebApp-01. Default types include Connected to, Depends on and Installed on, and admins can set suggested relationship types per CI type to reduce linking errors.
3. The Relationship Graph Drives Impact Analysis
The Relationship Graph shows CIs as nodes and relationships as lines, including the upstream and downstream CIs for any business service. Impact Analysis uses that map to simulate a change or failure, and Service Mapping ties CIs to the business service they support, with Online Checkout as the docs example.
4. Related CIs Attach to Incidents Automatically
Based on the dependency map, related CIs are associated with incident tickets automatically. A technician working an outage can then follow the dependencies to the CI that caused the business service failure.
5. Custom Rules Protect Sensitive Attributes
CI Custom Rules enforce your organization's policies while CIs are processed. For example, they can require a comment or note for any change to a CI's attributes, or stop users from changing hardware and software details directly.
All of this runs inside ServiceOps, which is ITIL 4 accredited through PeopleCert's Accredited Tool Vendor programme across 14 practices.
How Do You Choose a CMDB Tool?
You should judge a CMDB tool on how well it keeps data current, more than on how many CI types it can store. These are the capabilities we would check first.
Discovery coverage: Agent-based and agentless discovery across on-premises, virtual and cloud estates, including VMware, AWS, Azure and Nutanix.
Relationship mapping and impact analysis: A visual dependency graph that change and incident teams will actually open during their work.
ITSM integration: Native links between CIs and incident, problem, change and release records, so no separate database has to be synchronized.
APIs and rules: REST APIs and custom rules, so CI data can be validated and kept consistent with other systems.
A tool that combines these with service management, such as a unified observability and ITSM platform, removes the synchronization gap between the CMDB and the tickets that depend on it.
Build a CMDB Your Service Desk Can Trust With Motadata ServiceOps
A CMDB earns its place when the service desk relies on it every day. That only happens when the data is accurate, the scope stays controlled and every CI type has a named owner.
Start with your top 3 business services, automate discovery and link every incident and change to its CIs. That combination usually shows value within the first month, and the early return is what keeps the wider rollout funded. If you are comparing options, our list of enterprise CMDB tools sets out what to evaluate.
ServiceOps brings discovery, CI relationship mapping, impact analysis and ITIL 4 aligned service management into one platform, so your CMDB and your service desk work from the same record.
FAQs
What does CMDB stand for?
CMDB stands for configuration management database. It is the repository that stores configuration items, their attributes and the relationships between them, and it is the data source behind the ITIL 4 service configuration management practice.
Is a CMDB the same as an asset inventory?
No, an asset inventory lists what is owned. A CMDB records how each live component is configured and what depends on it, which is the relationship data that incident and change teams need.
How long does it take to build a CMDB?
A first phase covering your top 3 business services can usually be delivered in about 30 days if discovery is automated. Extending it to network, cloud and end-user devices typically takes a further 2 to 3 months.
Who should own the CMDB?
Ownership works best when it is split by CI type. Service owners maintain business service CIs, infrastructure leads own server and network data, and an IT asset manager owns end-user devices and licenses, with one configuration manager overseeing quality.
Is Motadata ServiceOps a CMDB tool?
Yes, ServiceOps includes a CMDB with agent-based and agentless discovery, a relationship graph, impact analysis and service mapping. The CMDB is licensed separately within ServiceOps, and it runs on SaaS or on-premises deployments.
Author
Drushti Shah
Senior Content Writer
Drushti is a senior content writer whose experience spans product marketing, brand communication, and B2B technology content. With a keen interest in how people interact with technology, she enjoys exploring new ways to make content more meaningful and accessible. She also incorporates AI-assisted writing approaches into content workflows, exploring how technology can reshape the way ideas are researched, developed, and communicated.